Demos don't survive contact with production.
Latency, hallucination, cost, and edge cases turn a great demo into an incident. The pod engineers for the day after launch and owns the result.
Senior engineers plus a delivery lead, in your repo within 5 days. We own outcomes, not hours.
Week-One Guarantee: replace any underperformer free within 14 days. Cancel in the first 30 days, pay nothing.


The team that builds the demo is rarely the team that can ship it.
Latency, hallucination, cost, and edge cases turn a great demo into an incident. The pod engineers for the day after launch and owns the result.
Engineers who have shipped real LLM systems are scarce. A full pod, senior engineers plus a delivery lead, lands in your repo this week.
Prompt injection, data leakage, and model abuse are real attack surfaces. The pod treats them as first-class from line one.
One pod takes your AI product from architecture to production, with no handoffs.
Production AI products, not prototypes. LLM integrations, AI agents, and RAG systems built on engineering practices that scale with your business.
A full-stack pod that ships AI-integrated products. Clean, maintainable code and modern workflows that cut your time to market.
Design AI-powered products users trust, from conversational interfaces to intelligent dashboards that drive real engagement.
Scale infrastructure for AI workloads. Cloud architecture for ML and LLM deployments, with CI/CD pipelines built for AI-specific needs.
Ship AI-enhanced apps across every platform. Fast, intelligent experiences with native AI integrations on web, iOS, and Android.
A named pod slots into how you already work, then owns the loop from first commit to measured outcomes. No offshore black box.
Senior engineers and a delivery lead join your standups, repo, and Slack. The pod maps the system and agrees on what “shipped” means.
The first production increment lands in weeks, not quarters. Weekly demos, real telemetry, and tight feedback loops keep the pod on the outcome, not on activity.
We track the outcomes that matter, latency, cost, adoption, and revenue, then harden and scale. Transparent reporting throughout, and we hand knowledge back so your team owns it.
You are not renting seats. You get a founder-vetted pod, a delivery lead who owns the outcome, and a partner that sticks around long after the first release.
We are builders at the core, and we love the craft. That same care goes into everything we ship for you, from the first commit to the last edge case.
We know what it takes to build a product, because we have done it. Our engineers have shipped inside high-functioning teams, at startups and at scale.
Our founders still personally hire every engineer against a high bar. We reject far more than we accept, and the bar only rises with each new hire.
We are not a staff-aug shop handing you seats to fill. We assemble a pod matched to what your project actually needs, so the shape of the team fits the work.
When a project hits the ceiling, our engineers take ownership and solve it instead of waiting to be told. They move problems forward, not just tickets.
Our engineers go past the code to become domain experts in your product. Coding is commoditized; what sets an engineer apart is obsession with your users.
You will not be left managing the team yourself. Every pod ships with an experienced delivery lead who owns planning, cadence, and communication.
We stay through the ups and the downs, not just the easy stretch. Our average client partnership runs three years, and many run longer.
We have engineered with AI and ML since 2017, years before ChatGPT made it a buzzword. It is native to how we build, not a capability we rebranded into after the hype.
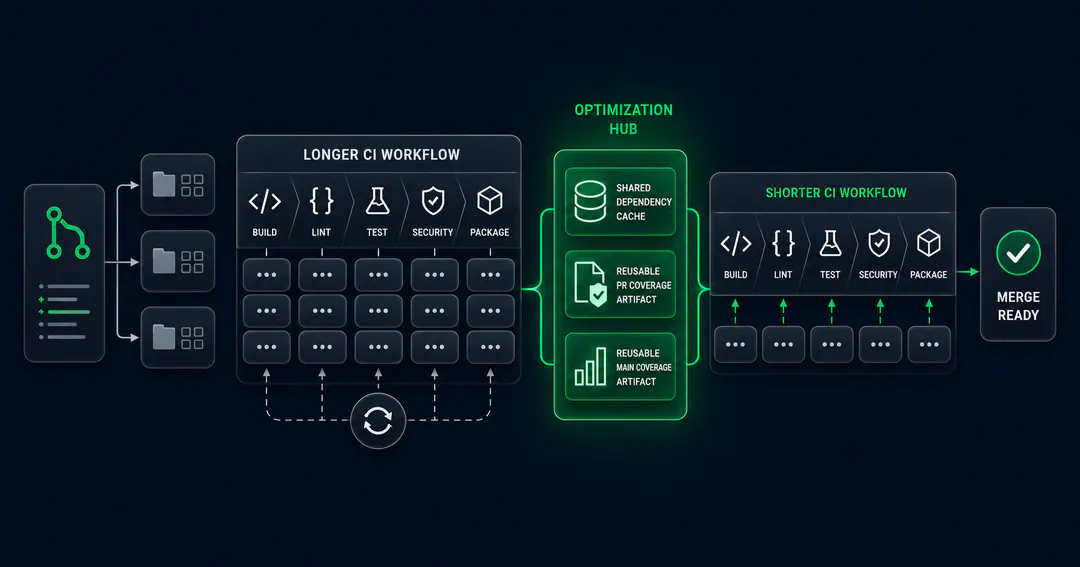
Restructuring a GitHub Actions pipeline for an EdTech scheduling platform: caching, artifact reuse, and cleaner job responsibilities took PR wait time from ~30 to ~10 minutes and cut projected CI cost by 73%.
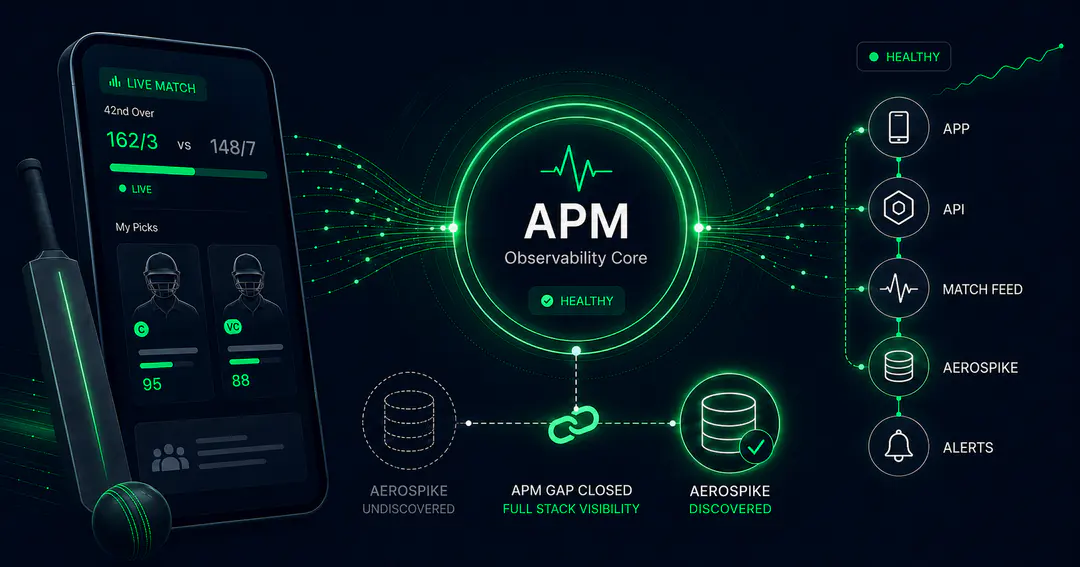
Helping an observability platform onboard a fantasy sports customer: Aerospike APM support, dashboard improvements, and stability fixes while sustaining 980M telemetry data points per minute through a live cricket season.
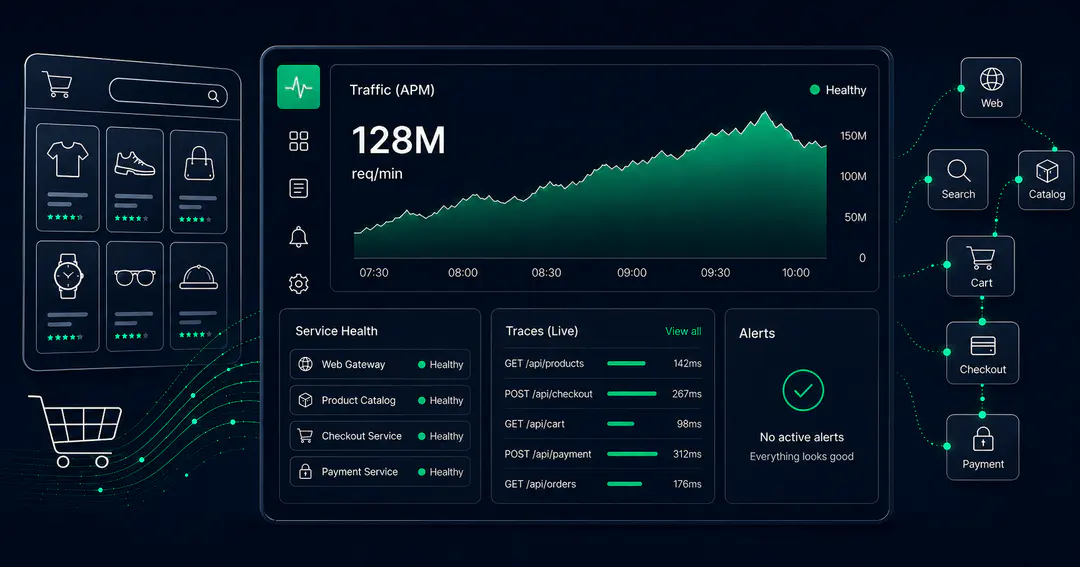
Helping an observability platform close APM and alerting gaps, fix log-heavy workloads, and support 300–400M telemetry data points per minute before a major ecommerce sale.
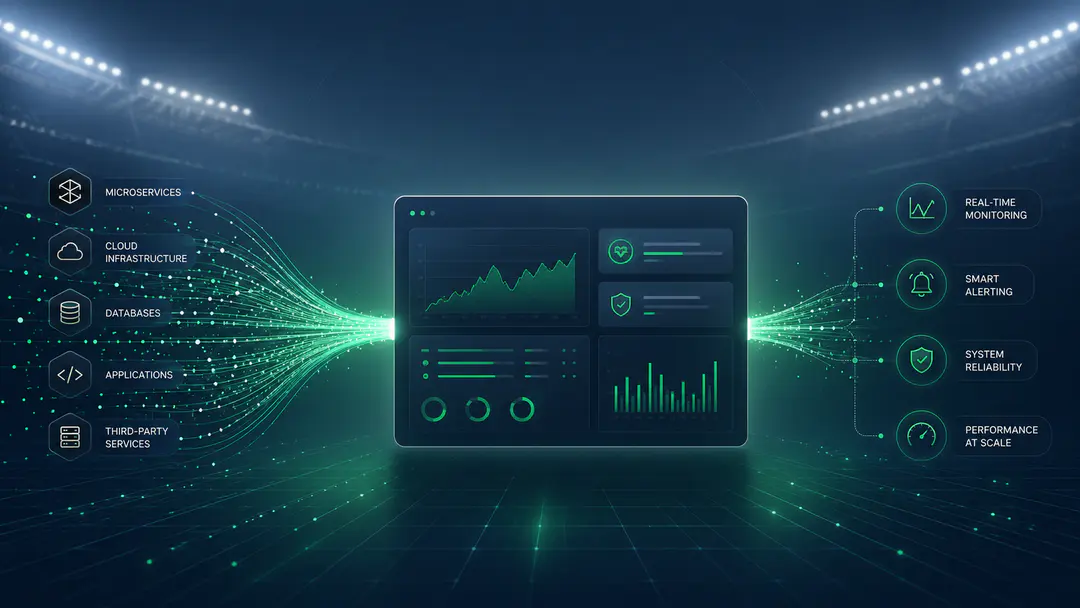
Embedding into a live-event observability platform to sustain 42M telemetry data points per minute across cricket and World Cup broadcasts, with a 99.9% SLA and 2-3 hour MTTR during match windows.
How Procedure re-architected Timely’s school scheduling platform to scale seamlessly across 30+ districts with faster onboarding and zero data fragmentation.

A case study on MCLabs’ rapid development of mission-critical communication software, from concept to production in record time.
“What started with one engineer nearly three years ago has grown into a team of five, each fully owning their deliverables. They've taken on critical core roles across teams. We're extremely pleased with the commitment and engagement they bring.”
The engineers who staff our pods care about craft. We mentor sharp people, ship work we’re proud of, and get trusted like owners from day one. A Certified Best Workplace, rated 4.9 on Glassdoor.


The Procedure pod builds production AI products: LLM applications, AI agents, retrieval-augmented generation (RAG) systems, and model-powered workflows across web and mobile. A pod pairs senior engineers with a delivery lead, so you get architecture, shipped code, and ownership of outcomes, not a prototype that stalls before production.
Procedure works with startup, scale-up, and enterprise product teams that need senior AI engineering capacity fast. A Procedure pod suits leaders who want to ship quickly without compromising quality, security, or reliability, and who prefer a team that owns outcomes over a body shop that bills hours.
A Procedure pod starts in 2-5 business days. Senior engineers and a delivery lead align to your stack and roadmap, then embed in your standups, repo, and Slack. The pod ships its first production increment in week one, so you see real code before most vendors finish onboarding.
Procedure delivers through a pod: senior engineers plus a delivery lead who owns outcomes. You can start with an AI Sprint to validate, then scale the pod for feature delivery and platform hardening. We shape team size to your roadmap, and you can cancel in the first 30 days at no cost.
With Procedure, AI Sprints typically range from $15K-$50K, and an ongoing pod starts around $50K per month depending on team size, complexity, and compliance needs. A pod bundles senior engineers and a delivery lead into one outcome-focused engagement, so you pay for shipped results, not staffed hours.
A Procedure pod ships a first production increment in week one. Validation and prototypes usually take 2-4 weeks, and MVP delivery often lands in 8-12 weeks. Larger enterprise rollouts can span 3-5 months depending on integrations and governance, with the pod owning outcomes throughout.
The Procedure pod builds secure-by-default systems with access controls, data-handling guardrails, and audit-ready engineering practices aligned to enterprise compliance. Security is treated as first-class from line one, not bolted on later, because prompt injection, data leakage, and model abuse are real attack surfaces in production AI.
A Procedure pod ships production code with your team, not slide decks. Senior engineers and a delivery lead own measurable outcomes, transfer knowledge, and build systems your team can operate long-term. If week one underperforms, we replace anyone free within 14 days, and you can cancel in the first 30 days.
Every week without a senior pod is another sprint of tech debt. Describe what you’re building and we’ll shape the pod that ships it in week one. First call is with an engineer, not a salesperson.
Book a 30-minute call →